Gradient is an AI infrastructure platform building an open, distributed alternative to centralized AI labs and data centers by harnessing a global mesh of idle, heterogeneous consumer devices to enable an Open Intelligence Stack (OIS).
Echo-2 decouples inference from training using a dual-swarm architecture that separates latency-sensitive model sampling on consumer "Actors" from high-throughput policy updates on centralized "Learners."
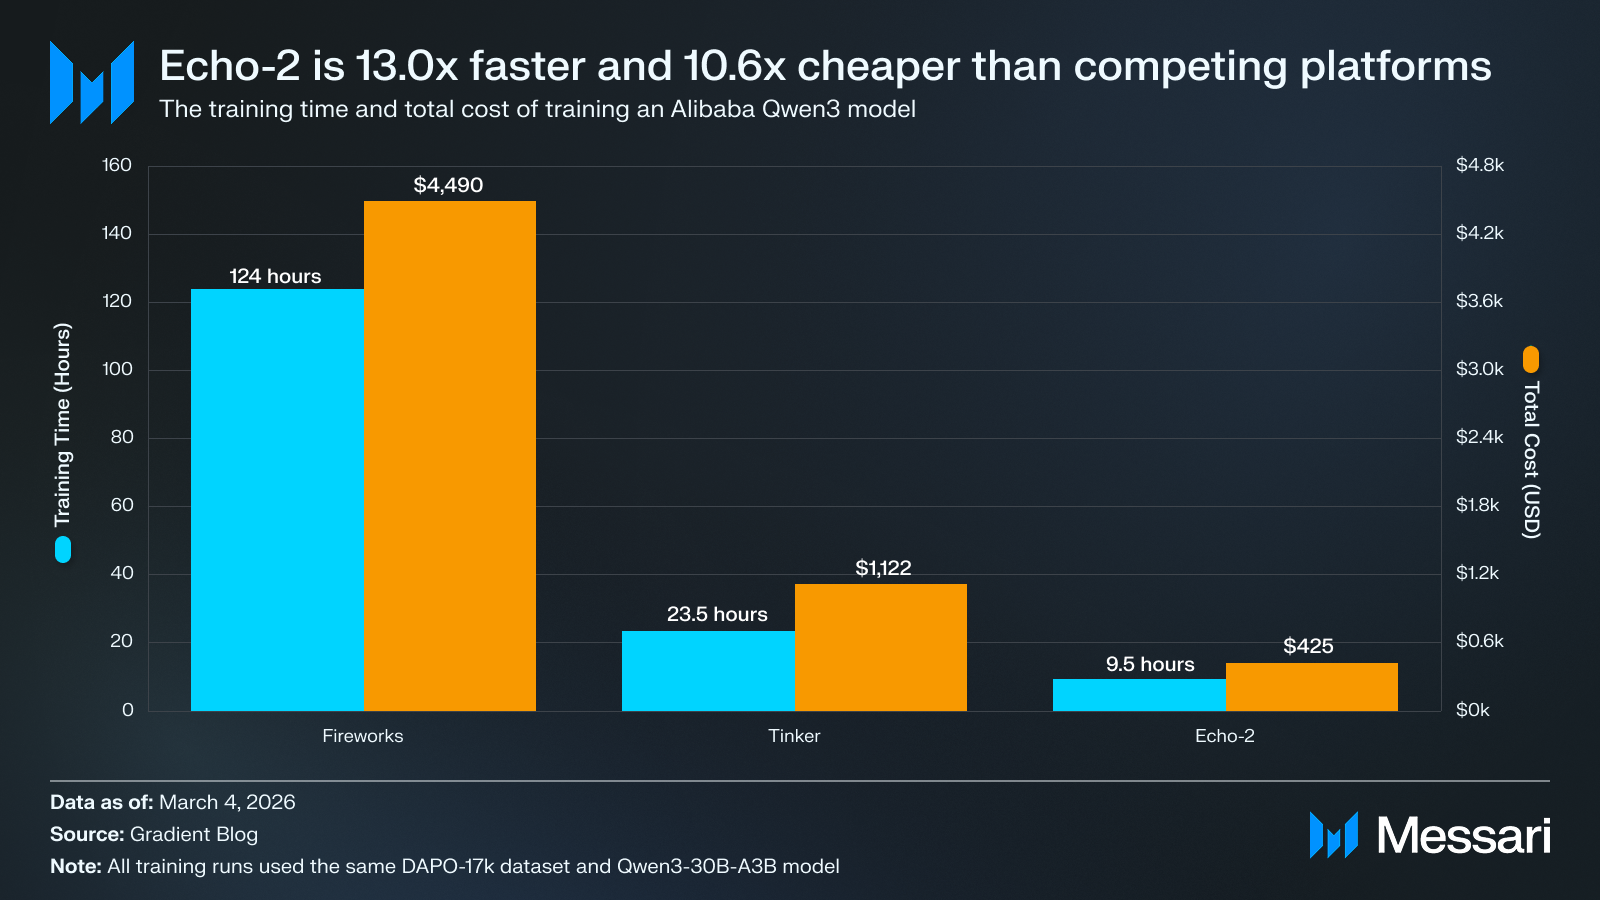
During initial benchmark testing, Echo-2 achieved a 10.6x drop in training costs, reducing total post-training expenses from $4,490 on a commercial cloud platform to just $425, while simultaneously increasing training velocity by 13.0x.
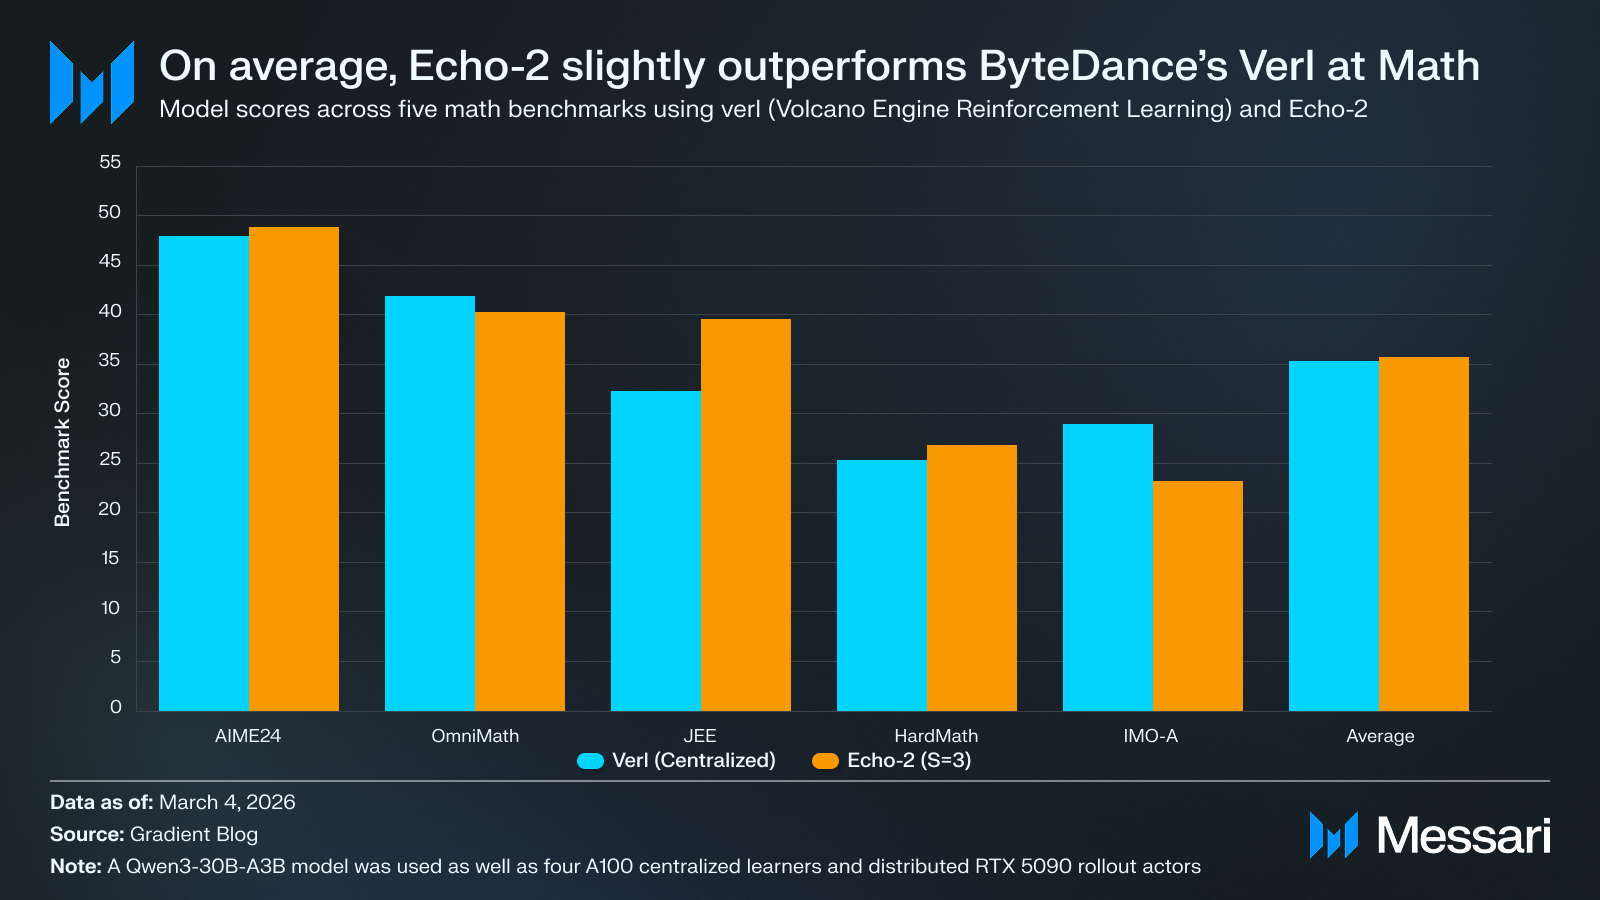
In comparative benchmark testing across five math reasoning datasets, Echo-2 achieved a mean reward score of 35.75 on a Qwen3-8B model, slightly outperforming ByteDance’s verl framework's 35.30 mean score. This research demonstrated that Echo-2 maintains full algorithmic fidelity while reducing cumulative hardware costs by 33–36% compared to expensive data center clusters.
Primer
Gradient is an AI research and development (R&D) lab developing open, distributed infrastructure as an alternative to today’s centralized AI labs. Unlike traditional AI frameworks that rely entirely on expensive, closed data centers, Gradient harnesses a global mesh of idle, heterogeneous devices, including datacenters, gaming GPUs, Apple Silicon, amongst other devices, to execute collaborative workloads. This approach unlocks latent compute globally, significantly lowering the cost of training and deploying large language models (LLMs). Gradient’s mission is to democratize access to AI, ensuring that users are not just consumers, but active creators and owners of sovereign, privacy-preserving intelligence.
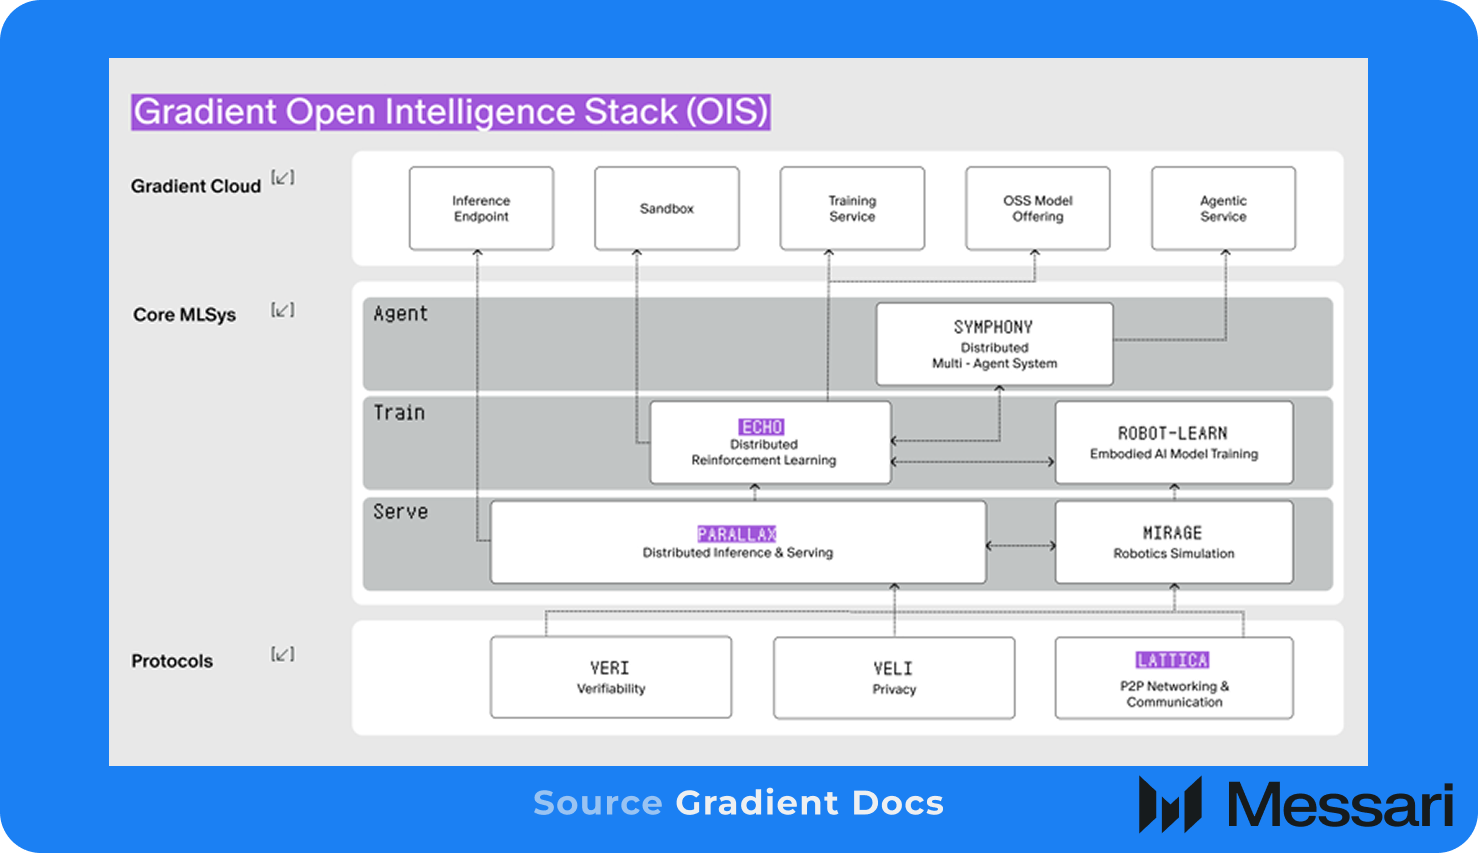
The platform’s foundation is built on the Open Intelligence Stack (OIS), an operating system and runtime for distributed AI models. A core component enabling this is Parallax, a distributed inference engine that shards and routes models across various hardware environments to deliver high-throughput, low-latency inference. Another foundational pillar is Echo, a distributed reinforcement learning (RL) framework that decouples inference from training. It employs a dual-swarm architecture that effectively decouples the latency-sensitive sampling process from the high-throughput weight updates. In this ecosystem, a swarm of consumer "Actors" generates massive amounts of environmental data via model sampling, while a separate swarm of "Learners" on high-end GPUs asynchronously processes these updates. This drastically reduces post-training costs while ensuring the training process remains resilient to node downtime.
Lattica, a universal peer-to-peer (P2P) data transmission protocol, powers these components by handling NAT traversal, peer discovery, and adaptive routing to securely move model weights and execution instructions across the open web.
The Open Intelligence Stack (OIS) is the foundational architecture of Gradient, serving as a distributed operating system and runtime for AI models. Unlike traditional AI frameworks that rely on closed, centralized data centers, the OIS enables a global mesh of machines, ranging from high-end gaming GPUs to everyday Apple Silicon devices, to collaboratively execute complex AI workloads.
Current AI R&D is constrained by centralized forces that pose significant risks to the future of AI and society at large:
Infrastructure Barriers: Advanced models are largely confined to specialized data centers and expensive, enterprise-grade GPUs, making personal and sovereign AI systems nearly impossible for the average user.
Resource Inefficiencies: Centralized systems are struggling with astronomical capital requirements for semiconductors and energy demands that power grids cannot sustain.
Monopolization: A few AI labs and hyperscalers control access to state-of-the-art (SOTA) models, posing risks of monopolistic control, privacy infringement, and systemic bias.
The Open Intelligence Stack solves these challenges by redefining model inference and training as a global, collaborative process. Instead of relying solely on H100 clusters, the OIS unlocks the world’s latent compute and stitches it into a verifiable, distributed execution engine. This architecture ensures that AI is a collective movement where the community owns the infrastructure, not just a centralized corporation.
The OIS operates through three foundational primitives that coordinate thousands of parallel computations across unmanaged networks:
Lattica (Communication): The universal peer-to-peer data motion engine. It acts as the "connective tissue" for the stack, handling NAT traversal and peer discovery to turn isolated machines into a globally addressable mesh.
Parallax (Compute): A distributed inference engine and "Sovereign AI OS". It enables large foundation models to be sharded and executed across heterogeneous devices, allowing everyday hardware to run trillion-class models that would otherwise be out of reach.
Echo (Orchestration): A distributed reinforcement learning (RL) framework that decouples inference from training. By offloading the compute-heavy sampling phase to a swarm of consumer devices, Echo reduces training costs by up to 10.6x compared to traditional cloud baselines.
Echo
Echo is a distributed reinforcement learning (RL) framework designed to solve the physical limitations of training large language models (LLMs) across geographically dispersed hardware. To understand Echo’s importance, we must distinguish between the two primary phases of model development:
Pre-training: The initial, compute-intensive phase where a model learns general patterns and facts from vast datasets to create a "base model."
Post-training: The refinement phase, where the model is taught to follow instructions, avoid harmful outputs, and excel at specific tasks.
While pre-training builds raw intelligence, post-training transforms a base model into a functional, consumer-ready product.
Traditional RL training is ill-suited for distributed environments because it relies on a synchronous, serial loop. In a standard data center, GPUs alternate between sampling (generating responses) and training (updating gradients). This "stop-and-start" approach causes significant hardware idling. When attempted over the public internet, high latency makes this serial approach practically impossible; nodes spend the vast majority of their time waiting for weight updates rather than performing computation.
Dual-Swarm Architecture
Echo fundamentally alters the economics of RL by decoupling the compute-intensive rollout phase, where the model generates a response and receives a reward, or a numerical score based on how well it followed instructions, from the learning phase, where the system calculates gradients, which are mathematical instructions for improvement, to update the model’s weights, the internal policies that determine its behavior.:
The Inference Swarm: A fleet of low-cost, consumer-grade GPUs (Edge Hosts) that perform the "sampling". They generate millions of trajectories and environment data needed for the model to learn.
The Training Swarm: A stable cluster of high-performance GPUs (e.g., A100 or H100) that performs the actual policy optimization and gradient updates.
Decoupling allows each swarm to scale independently based on demand. This enables research teams to run a high velocity of experiments at a fraction of the cost of centralized providers, lowering the barrier to entry for high-performance RL.
Principled Synchronization
Echo utilizes two distinct synchronization protocols that users can toggle based on their needs:
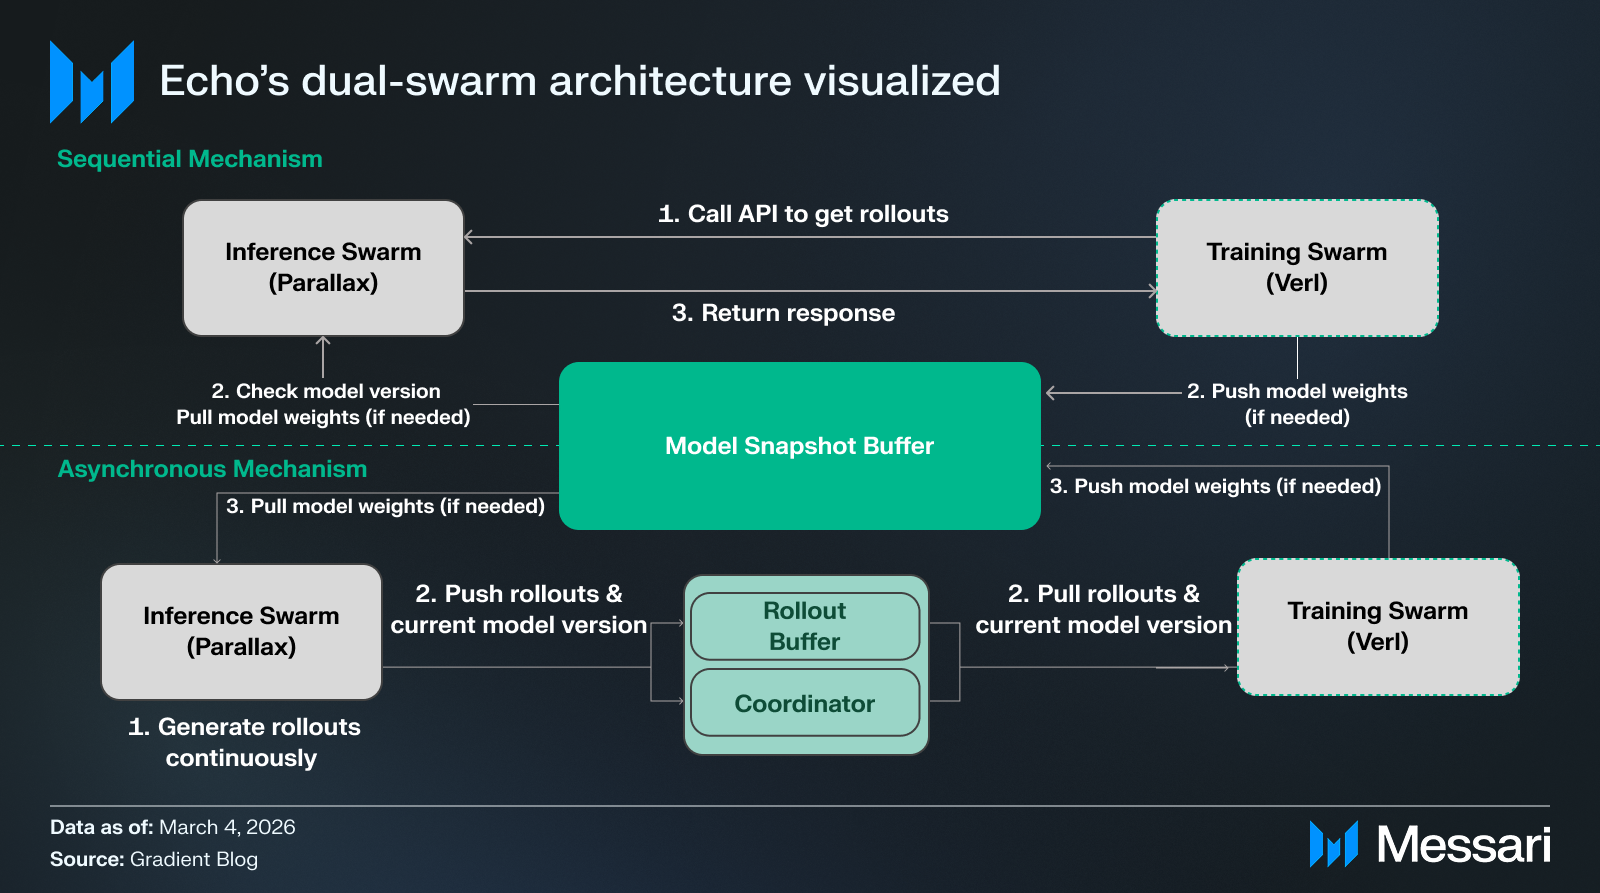
Sequential Mechanism (Most Accurate): Prioritizes mathematical precision by requiring the Training Swarm to manually "pull" data from the inference nodes. Before providing a response, each inference node must verify and update its local model weights to match the trainer exactly. While this introduces a brief waiting period, it mirrors the strict reliability of traditional, centralized training environments and minimizes the risk of statistical errors.
Asynchronous Mechanism (Most Efficient): Focuses on maximizing the total volume of work processed by the network. Inference nodes continuously "push" responses into a shared “Rollout buffer”, allowing the Training Swarm to draw from this pool and perform updates without pausing to wait for the network.
The Model Snapshot Buffer acts as the central repository for the model's weights, while the Inference and Training Swarms interact with it differently depending on the chosen mechanism. In the sequential flow, the Training Swarm manually "calls" for data, forcing the Inference Swarm to pull the latest weights before returning a response, whereas the asynchronous route allows for continuous data generation and "pushing" to a Rollout Buffer, where the Trainer pulls updates and cycles new weights back to the Snapshot Buffer as the Coordinator manages version skew in the background.
Echo-2
Echo-2 is the second generation of Gradient’s RL framework, optimized for large-scale distributed rollout execution over wide-area networks (WAN). It moves beyond simple decoupling to treat WAN constraints as controllable parameters.
The key breakthrough of Echo-2 is its ability to handle policy staleness. In a decentralized network, the Inference Swarm may generate trajectories using a policy version that lags behind the current learner state. Echo-2 treats bounded staleness, the degradation of model performance when the data it was trained on no longer reflects current real-world conditions, as a user-controlled parameter, typically allowing rollouts to lag 3–6 training steps behind the learner. This temporal lag enables concurrent rollout generation, policy dissemination, and training. Research confirms that, for modern objectives like Group Relative Policy Optimization (GRPO), moderate staleness does not degrade final model quality but enables 100% hardware utilization across the mesh.
To mitigate the bottleneck of distributing model weights to hundreds of actors, Echo-2 employs peer-assisted pipelined broadcast. Instead of a "push-to-all" strategy that exhausts the learner's uplink, actors are organized in a tree topology where they immediately forward received snapshots to peers. This ensures dissemination time scales logarithmically rather than linearly with fleet size.
Echo-2 treats H200 clusters, consumer 5090s, and other idle instances as a unified logical compute mesh. By utilizing efficient Asynchronous RL with bounded staleness, Gradient can orchestrate distributed, unreliable GPUs, hardware that is significantly cheaper because it lacks guaranteed availability. When a node drops out or prices shift, the scheduler automatically reroutes tasks and adjusts the mix. This allows the network to convert raw, volatile compute power into stable, reliable post-training infrastructure.
Three-Plane Modular Architecture
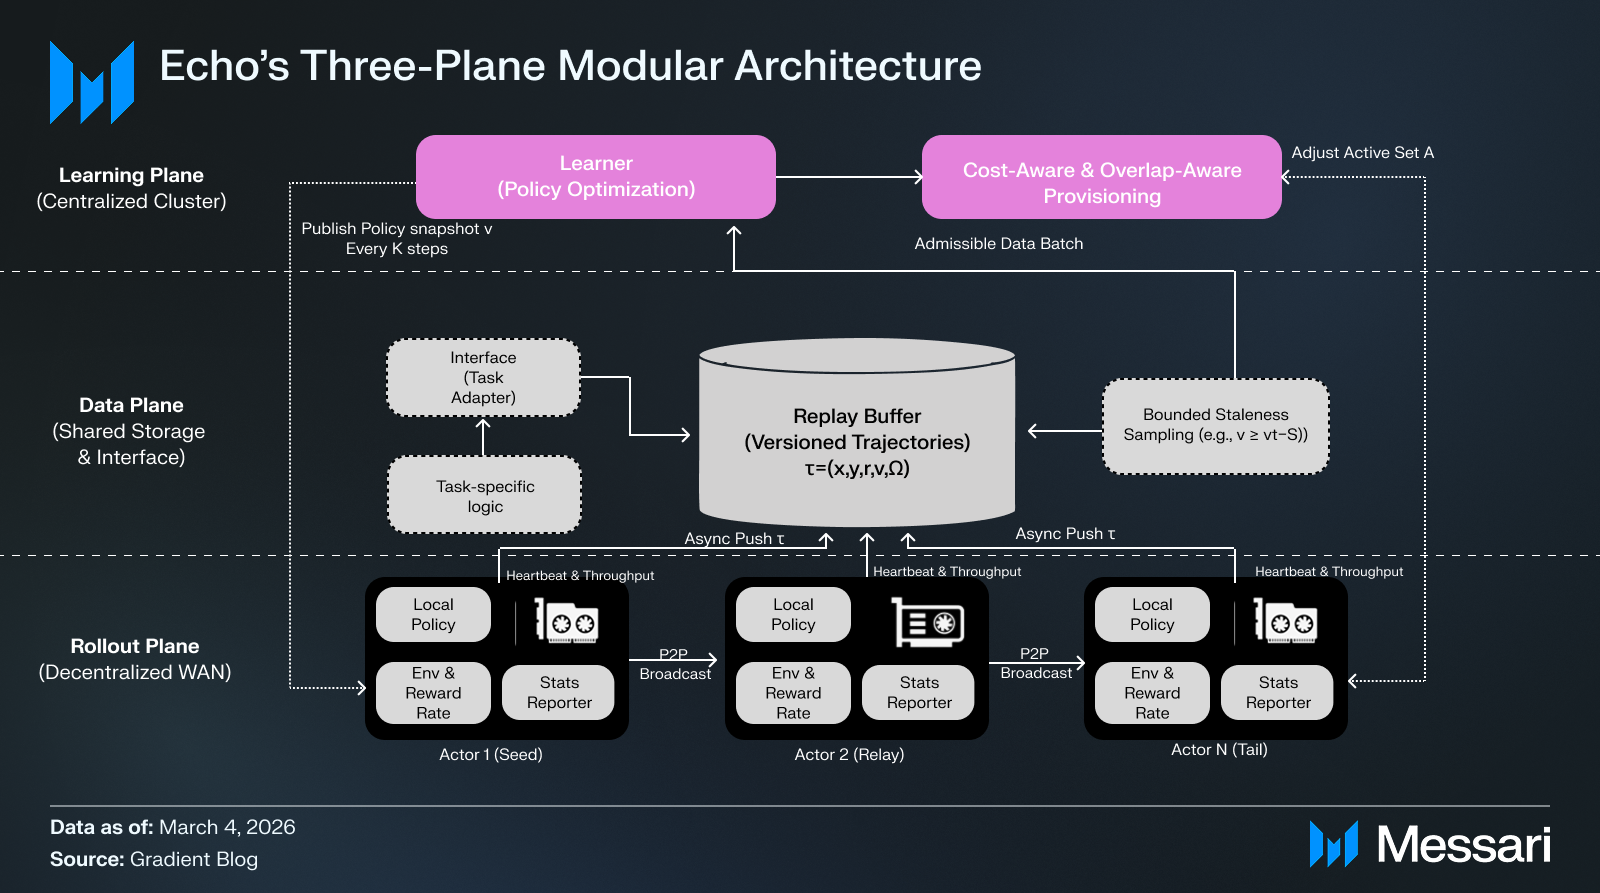
Echo-2’s three-plane decomposition enables the system to offload the compute-heavy sampling phase (Rollout Plane) to cheaper, distributed resources while maintaining high-performance policy optimization on a stable cluster (Learning Plane).
Learning Plane
The Learning Plane serves as the brain of the system, running on a stable set of high-performance data center GPUs.
Policy Optimization: It consumes trajectory batches from the Data Plane to perform gradient updates using standard algorithms like Proximal Policy Optimization (PPO) or GRPO.
Version Management: Every κ steps, it publishes a new, immutable policy snapshot (v) to the Rollout Plane.
Cost-Aware Provisioning: A scheduler monitors the effective throughput of the rollout fleet and adjusts the active worker set to keep the learner saturated at the lowest possible cost.
Data Plane
The Data Plane acts as the connective tissue, abstracting task-specific logic away from the underlying infrastructure.
Task Adapters: They define the specific prompts, reward functions, and the conversion of trajectories into training signals.
Replay Buffer: This shared storage manages version-tagged trajectories (τ=(x,y,r,v,Ω)).
Bounded Staleness Sampling: To maintain training stability, it filters data, ensuring the learner only consumes rollouts from policies that are at most S steps old (e.g., v ≥ vt−S).
Rollout Plane
The Rollout Plane is a global swarm of heterogeneous, often "unreliable" consumer-grade hardware (e.g., RTX 5090s, Apple Silicon).
Distributed Generation: Workers generate millions of trajectories by running inference forward passes and reward evaluations.
Peer-Assisted Pipelined Broadcast: Workers forward model snapshot chunks to one another immediately upon receipt, enabling them to switch to the latest policy and roll out faster.
Asynchronous Push: Completed trajectories are pushed asynchronously to the Data Plane's replay buffer, allowing generation and training to overlap seamlessly.
Performance Evaluation
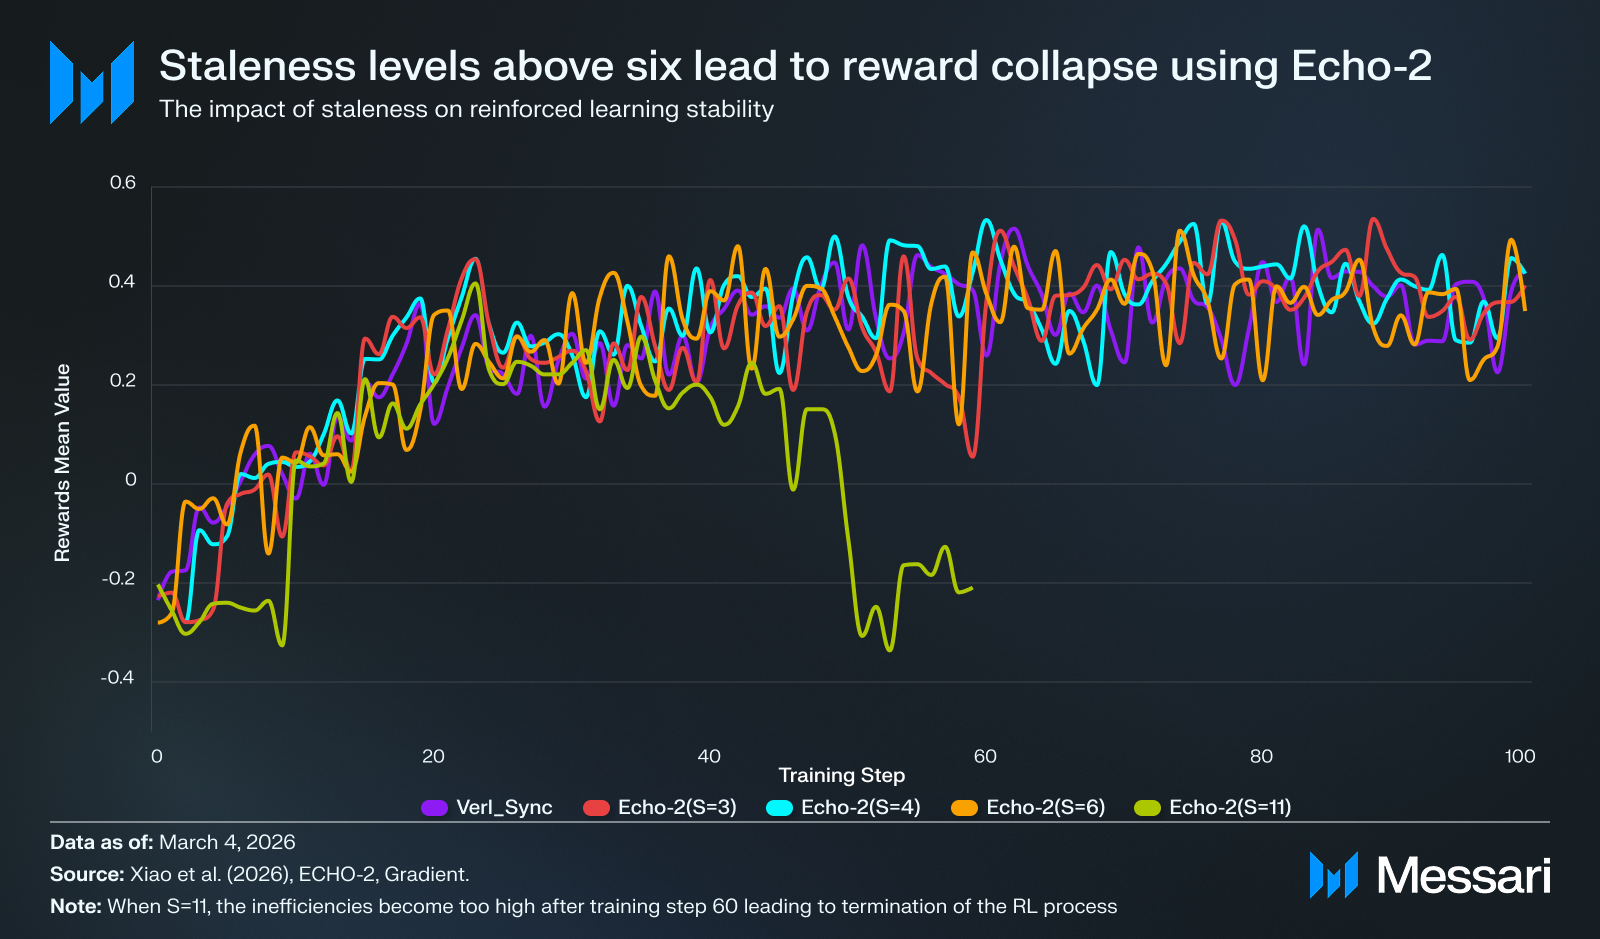
In distributed RL post-training experiments on the AIME24 benchmark, Echo-2 demonstrated that orchestrating a decentralized swarm of consumer-grade RTX 5090s can match the RL quality of centralized A100 clusters while significantly reducing operational costs. Under wide-area network constraints, Echo-2 maintained robust performance for staleness levels up to S≤6, achieving target quality at a fraction of the hardware rental price ($0.35/hr for RTX 5090 vs. $3.06/hr for A100).
Cost-Efficiency and Speed
Gradient benchmarked the post-training of a Qwen3-30B model on the DAPO-17k dataset. The team ran the same training job across Fireworks, Thinking Machines’ Tinker, and Echo-2 to directly compare cost and training time. Echo-2 reduced the total training costs from Fireworks’ $4,490 cloud baseline to just $425, achieving a 10.6x increase in cost efficiency. The training job was also completed 67.8% to 92.3% faster using Echo-2 (9.5 hours vs 23.5 to 124 hours).
Model Quality and Resilience
While speed and cost are important factors, Echo-2’s resilience in handling unreliable distributed hardware must also be considered. The Gradient team conducted internal stress tests using consumer-grade GPUs (RTX 5090s) via Parallax to serve as rollout actors for a centralized 4×A100 learner. Testing on high-stakes mathematical reasoning tasks revealed that Echo-2 maintains competitive scores even under wide-area network constraints. On a suite of five math benchmarks, Echo-2 achieved a mean score of 35.75, slightly exceeding ByteDance’s verl baseline of 35.30. This confirms that the framework can deliver enterprise-grade throughput and quality while using hardware that is significantly cheaper because of its lack of guaranteed availability.
The breakthrough enabling this resilience is the management of bounded staleness (S). Echo-2 treats staleness as a controllable parameter, typically allowing rollouts to lag the learner by 3–6 training steps. This temporal slack allows for the generation of rollout and the dissemination of policy to overlap seamlessly with training. While moderate staleness budgets of S=3 to S=6 provide robust convergence and near-100% hardware utilization, testing indicates a clear upper bound; at S=11, the system observes complete divergence.
Logits
With Echo-2 establishing that research velocity is no longer capped by infrastructure budgets, Gradient is now productizing this framework through Logits, an RL-as-a-Service (RLaaS) platform.
Logits abstracts away the complex coordination required for distributed orchestration, offering a streamlined solution for scaling alignment workloads. The platform provides:
Managed Infrastructure: A turnkey system to handle the synchronization between centralized learners and distributed rollout fleets.
Global Scale: Direct integration with Parallax to leverage a global mesh of inference capacity.
Model Ownership: A shift away from renting closed-source intelligence. Users can fine-tune open models on proprietary data and retain full ownership of the resulting weights.
The Logits waitlist is currently open to university students and researchers looking to transition from static evaluation to high-velocity, distributed reinforcement learning.
Closing Summary
Gradient is building the Open Intelligence Stack (OIS) to systematically diminish the capital and hardware barriers to AI R&D, exacerbated by centralized infrastructure. Echo-2 neutralizes the latency tax of WANs, achieving up to a 10.6x reduction in post-training costs. By transforming a fragmented mesh of consumer hardware into resilient AI infrastructure, Gradient enables open-source contributors and smaller labs to iterate at speeds previously reserved for large corporations and VC-backed startups.
As the network transitions from research to production via Logits, it establishes the first onchain platform for RL-as-a-Service (RLaaS). Logits abstracts the complexity of distributed orchestration, allowing researchers to trade the "closed" gatekeeping of centralized providers for the sovereign, resilient compute of a global mesh. This transition positions Gradient as a foundational candidate for a future where specialized, community-owned AI models replace the capital-intensive, monolithic cloud models of today.
This report was commissioned by Gradient Network All content was produced independently by the author(s) and does not necessarily reflect the opinions of Messari, Inc. or the organization that requested the report. The commissioning organization may have input on the content of the report, but Messari maintains editorial control over the final report to retain data accuracy and objectivity. Author(s) may hold cryptocurrencies named in this report. This report is meant for informational purposes only. It is not meant to serve as investment advice. You should conduct your own research and consult an independent financial, tax, or legal advisor before making any investment decisions. Past performance of any asset is not indicative of future results. Please see our Terms of Service for more information.
No part of this report may be (a) copied, photocopied, duplicated in any form by any means or (b) redistributed without the prior written consent of Messari®.
Youssef is a Research Analyst on the Protocol Research team. Prior to joining Messari, Youssef was a Product Analyst at Fidelity Digital Assets. Youssef graduated from Northeastern University, where he led the Northeastern Blockchain club as President.
Youssef is a Research Analyst on the Protocol Research team. Prior to joining Messari, Youssef was a Product Analyst at Fidelity Digital Assets. Youssef graduated from Northeastern University, where he led the Northeastern Blockchain club as President.